Introducing Kimi K3.1 Pro
Kimi K3.1 Pro vs DeepSeek API: A Deep-Dive Comparison for Production Teams Most API selection decisions get made in the first thirty minutes of a demo.
Kimi K3.1 Pro vs DeepSeek API: A Deep-Dive Comparison for Production Teams
Most API selection decisions get made in the first thirty minutes of a demo. Someone pastes a prompt, a model returns something impressive, and the team moves on to pricing. Six weeks later the same team discovers that their p95 latency is triple what the demo suggested, that retries are silently inflating costs by 30%, and that the SDK's error semantics don't map cleanly onto their existing retry logic.
This deep dive is about avoiding that outcome. The Kimi K3.1 Pro vs DeepSeek API decision is not a leaderboard question — it's an engineering and operations question, and it deserves the same rigor you'd apply to picking a database. Below, we'll work through a comparison framework, capability-by-capability evaluation, benchmarking methodology you can reproduce, production lessons, and a decision matrix you can hand to your team. Where vendor documentation is the only source of truth, we'll flag it rather than assert a number.
1. Kimi K3.1 Pro vs DeepSeek API: Comparison Framework
Before comparing features, agree on what "better" means for your workload. A reasoning-heavy agent platform and a high-volume summarization pipeline have almost nothing in common in terms of what makes an API good.
The dimensions that actually separate providers in production are: workload fit (does the model's strength match your task distribution?), latency shape (median vs tail, and time-to-first-token under streaming), cost predictability (effective cost per successful task, not per token), integration effort (SDK parity, error semantics, streaming format), reliability (rate-limit behavior, retry safety), and governance (data residency, logging, contractual terms).
Score each dimension on your own scale, but weight them by blast radius. A 10% quality improvement on a task you run 50 times a day is worth less than avoiding a latency regression on a user-facing chat endpoint.
What Kimi K3.1 Pro Brings to LLM API Alternatives
Kimi K3.1 Pro enters the LLM API alternatives conversation as a candidate for teams that want to diversify away from a single provider or that have hit a quality or availability ceiling. Because model capabilities, context windows, and rate-limit tiers change frequently, treat every claim — including the ones in this article — as something to confirm against the provider's current official documentation and changelog before you architect around it.
Practically, evaluating Kimi K3.1 Pro means asking three questions: What access patterns does the API support (sync, streaming, batch)? How is versioning handled — can you pin a model snapshot for reproducibility? And what are the documented limits on context, concurrency, and request size?
DeepSeek API Comparison Criteria: Latency, Cost, Quality, Reliability
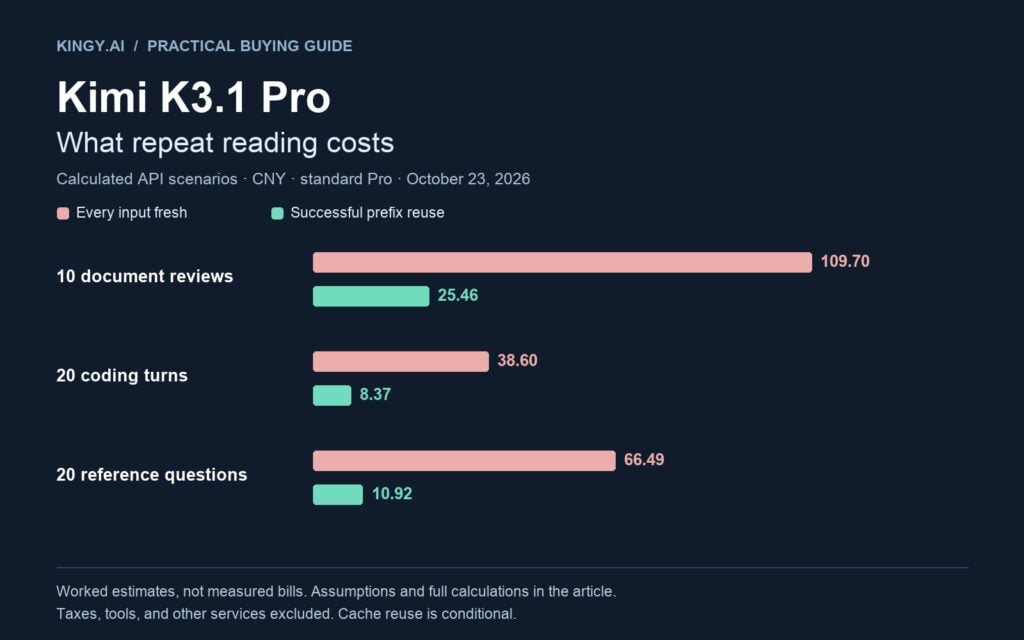
A balanced DeepSeek API comparison scorecard should include p50 and p95 latency measured from your infrastructure, not from a shared benchmarking blog, plus throughput under your expected concurrency. Output quality should be measured on a task-specific eval set, not a general benchmark. Retry behavior matters more than people expect: an API that returns clean, typed errors with a Retry-After hint is dramatically cheaper to operate than one that returns opaque 500s under load. And cost should be expressed as effective cost per successful task — total spend divided by tasks that passed your quality bar — which captures retries, truncations, and re-runs in one number.
How to Read Vendor Claims Without Overfitting to Benchmarks
Benchmark contamination is real: public eval sets leak into training data, and a model that scores well on a public reasoning benchmark may behave very differently on your proprietary domain. Prompt sensitivity is the other trap — a two-point swing from rephrasing the system prompt is common, and cherry-picked tasks in a launch post are usually the ones the model does best on. Demo quality and production reliability are separate properties; a model can be excellent and still be a poor operational choice if its tail latency is unstable.
2. Kimi K3.1 Pro vs DeepSeek API: Core Capability Comparison
This section is deliberately evidence-oriented. Any specific performance number for either provider should be validated with a proof of concept against your own prompts before it drives a decision.
Reasoning, Coding, and Long-Context Workloads
Build three small test suites that mirror your actual traffic. For reasoning, use multi-step tasks where you can check the final answer mechanically — arithmetic with verifiable outputs, multi-hop retrieval questions, constraint-satisfaction problems. For coding, use tasks from your own codebase: generate a function that must pass existing tests, refactor a file, or produce a migration that runs cleanly against a schema. For long context, place a specific fact deep in a long document and ask a question that requires it — testing recall at 25%, 50%, and 90% of the advertised context window, because recall typically degrades unevenly across the window.
Instruction following deserves its own suite. Format constraints ("return only JSON", "use exactly three bullets") fail silently in ways that break downstream parsers, so test them explicitly and measure the failure rate rather than eyeballing outputs.
API Ergonomics and Integration Complexity
Compare authentication flows, SDK availability and language coverage, streaming event formats, request/response size limits, structured output support, tool-calling patterns, and error semantics. The details that bite in production are usually boring: whether streaming chunks include usage accounting, whether the SDK retries by default (and with what backoff), whether tool-call arguments stream incrementally or arrive as one blob, and whether rate-limit errors are distinguishable from server errors by status code.
Streaming, Tool Use, and Output Reliability
Streaming isn't just a UX feature — it's a timeout strategy. Measure time to first token separately from total generation time, because users judge responsiveness by the former. Then test partial-response handling: if your client disconnects mid-stream, are you still billed, and does the provider clean up the request? For tool use, test with deliberately malformed tool schemas and missing arguments to see how the model recovers. A tool-calling implementation that fails gracefully with a structured error is worth more than one that occasionally emits syntactically valid but semantically wrong JSON.
3. Evaluating Kimi K3.1 Pro as a DeepSeek API Alternative
Whether a Kimi K3.1 Pro API alternative makes sense depends on what triggered the evaluation in the first place.
Migration Signals: When a Kimi K3.1 Pro API Alternative Makes Sense
Legitimate triggers include a measurable quality gap on your eval set, a latency bottleneck you can't engineer around, a pricing change that breaks your unit economics, regional availability or residency requirements, a mandate to diversify vendor risk, or a specific workload — say, long-document analysis — where one provider clearly outperforms. Illegitimate triggers include a viral benchmark screenshot and a single impressive demo.
Compatibility Checklist for Existing DeepSeek Integrations
Before switching any traffic, inspect: assumptions baked into your prompts (some models need different system-prompt phrasing to behave consistently), token accounting (tokenizers differ, so your context budgeting and cost model both shift), maximum context length, rate limits and their reset semantics, streaming chunk format, SDK method parity, observability hooks (does your tracing capture the new provider's request IDs?), and fallback logic. The last one is the most commonly overlooked — teams often discover their fallback path was never actually exercised.
Hidden Costs in LLM API Alternatives: Rate Limits, Retries, and Token Accounting
The costs that don't show up in per-token pricing are the ones that kill budgets. Retry storms multiply spend during incidents. Queuing delays push you into expensive over-provisioning. Failed generations still bill. Context bloat — stuffing the full conversation history into every request because it's easier than summarizing — scales quadratically in cost as sessions grow. And output-length variance means a model that's "cheaper per token" can be more expensive per task if it's consistently more verbose.
4. Performance and Cost Benchmarking Methodology
A reproducible benchmark is the single highest-leverage artifact you can build during evaluation. Here's a minimal harness shape:
import time, statistics

def measure(client, model, prompts, concurrency=8):
    latencies, tokens = [], 0
    for batch in chunked(prompts, concurrency):
        start = time.perf_counter()
        results = parallel_map(lambda p: client.complete(model, p), batch)
        latencies.append(time.perf_counter() - start)
        tokens += sum(r.usage.total_tokens for r in results)
    latencies.sort()
    return {
        "p50": statistics.median(latencies),
        "p95": latencies[int(len(latencies) * 0.95)],
        "effective_cost": tokens / len(prompts),
    }
Designing a Fair Latency and Throughput Test
Separate cold starts from warm latency — the first request after a period of inactivity is often several times slower, and if your traffic is bursty, that's your real user experience. Measure streaming time-to-first-token independently. Run at your expected concurrency and at 2× to see where the curve bends. Report p95, not averages: averages hide the tail that users actually complain about.
Measuring Quality with Task-Specific Evaluation Sets
Build a gold-standard set of 50–150 examples drawn from real traffic, with a written scoring rubric. Where possible, score mechanically (does the code pass tests? does the JSON parse? is the answer string correct?). Where you need human review, use two reviewers and measure agreement — if they disagree often, your rubric is the problem. Track prompt versions alongside scores, because a prompt change and a model change confounded together teach you nothing.
Total Cost of Ownership Beyond Per-Token Pricing
Effective cost per successful task = (token spend + retry overhead + failed generations) ÷ passing tasks. Add engineering maintenance for adapters, observability costs for logging and tracing, fallback infrastructure, and the human cost of vendor management. For low-volume workloads, engineering time dwarfs token spend — a provider that saves you two days of integration work is worth a meaningful per-token premium.
5. Real-World Implementation and Production Lessons
The failure modes below show up in almost every provider migration, and they're all preventable with a two-week canary.
Common Pitfalls When Switching Between Kimi K3.1 Pro and DeepSeek API
Prompt drift is the most common: system prompts tuned on one model produce different behavior on another, especially around verbosity and refusal patterns. Tokenizer differences break context budgeting in ways that only surface when you hit the limit. Output-format assumptions — "it always returns valid JSON" — become production incidents. Timeout mismatches cause silent failures when a client timeout fires slightly before the provider's. Rate-limit surprises appear at concurrency levels you never tested. And insufficient regression testing means you find all of the above in production.
Lessons from Production: Fallbacks, Observability, and Version Pinning
Always pin model versions explicitly. An unannounced update behind a floating alias can change output distributions overnight. Route by capability, not by brand: a router that sends long-context requests to one model and cheap classification requests to another captures most of the cost benefit with none of the lock-in. Log structured request metadata — model, version, token counts, latency, outcome — and alert on error-rate and cost-per-hour spikes, not just availability. Deploy prompt changes by canary, exactly as you would code.
Practical Integration Pattern with Mydeepseekapi for DeepSeek v3 & r1
For teams that choose the DeepSeek route, Mydeepseekapi is an operational option worth evaluating alongside direct access: it provides integration for DeepSeek v3 and r1 models with fast response times, transparent pricing, and minimal setup. The practical pattern is to treat it as a routing target behind your existing abstraction layer — one adapter, one set of retry and logging semantics — so that swapping or adding providers stays a configuration change rather than a refactor. It's not positioned as a replacement for Kimi K3.1 Pro; it's a way to reduce the operational friction of the DeepSeek side of the comparison.
6. Security, Compliance, and Operational Fit
Governance questions decide more production adoptions than raw model quality does.
Data Residency, Logging, and Privacy Considerations
Confirm where prompts are processed, how long they're retained, whether they're used for training, what access controls exist, and how PII is handled. Get the retention policy in writing. If you operate under GDPR, HIPAA, or sector-specific rules, involve legal before the proof of concept, not after — a model that fails your compliance review is a model you can't use regardless of its benchmark scores.
Rate-Limit Behavior and Error Recovery
Distinguish rate-limit errors from server errors and handle them differently. Exponential backoff with jitter is table stakes; idempotency keys matter for anything that triggers side effects; circuit breakers prevent a degraded provider from cascading into your whole system. Test your retry logic by deliberately exhausting limits in staging.
When to Use Kimi K3.1 Pro and When Not To
Kimi K3.1 Pro may be a strong fit when you need a second source for quality or availability, when your workload matches its documented strengths, or when diversification itself is the goal. It may be a weaker fit when your team is small and integration effort is the binding constraint, when you need a specific SDK or tooling ecosystem, or when your compliance posture requires a provider whose terms you haven't yet reviewed. Neither is a universal answer — which is precisely why the comparison should be empirical.
7. Mydeepseekapi in the LLM API Alternatives Mix
Mydeepseekapi belongs in the evaluation set for teams leaning toward DeepSeek models, particularly when setup time is the constraint.
How Mydeepseekapi Supports DeepSeek v3 & r1 Integration
It provides integration for DeepSeek v3 and r1 through a straightforward API surface, so you can add these models to existing workflows without building provider-specific plumbing from scratch. For a proof of concept, that means hours rather than days.
Transparent Pricing and Fast Response Times for AI Apps
Transparent pricing removes one of the biggest sources of evaluation friction — the inability to forecast cost per feature. Fast response times matter for user-facing endpoints, and both are things you should verify in your own benchmark rather than take on faith.
Zero Setup Hassle: Workflow Fit and Developer Experience
Minimal setup shortens the loop between "we should test this" and "we have data," which is the single biggest accelerator in any API comparison. If onboarding takes five minutes instead of a day, you'll actually run the experiment.
8. Decision Guide: Kimi K3.1 Pro vs DeepSeek API for Your Stack
Workload-Based Recommendations
| Workload | Priority criteria | Notes |
|---|---|---|
| User-facing chat | Time-to-first-token, p95 latency | Streaming is mandatory |
| Coding assistant | Output quality on your repo, tool-use reliability | Test with your own tests |
| RAG / long-doc QA | Long-context recall, cost per query | Test recall deep in the window |
| Agents / tool use | Structured output, error semantics, retry safety | Test malformed tool calls |
| Summarization | Cost per task, output-length control | Verbosity drives cost |
| Batch processing | Throughput, rate limits, async support | Cheap and slow may be optimal |
Proof-of-Concept Checklist Before Committing
Define test prompts from real traffic. Score with a written rubric and mechanical checks. Set explicit latency targets (p50 and p95) and cost ceilings per task. Exercise failure handling — force timeouts, rate limits, and malformed outputs. Complete the security review. Write down the fallback plan and actually trigger it once. Only then move traffic.
Comparison Matrix for LLM API Alternatives
| Dimension | What to verify | Kimi K3.1 Pro | DeepSeek API | Mydeepseekapi |
|---|---|---|---|---|
| Quality | Score on your eval set | Measure | Measure | DeepSeek v3 / r1 |
| Latency | p50, p95, TTFT | Measure | Measure | Fast response times |
| Cost predictability | Cost per successful task | Measure | Measure | Transparent pricing |
| Integration effort | Adapter hours | Measure | Measure | Minimal setup |
| Operational support | Docs, status, changelog | Verify | Verify | Verify |
| Governance | Residency, logging, terms | Verify | Verify | Verify |
Conclusion
The Kimi K3.1 Pro vs DeepSeek API question doesn't have a universal answer, and any article that gives you one is selling something. What it does have is a repeatable process: define weighted criteria against your real workload, build a small gold-standard eval set, measure latency shape and effective cost per successful task, canary the migration, and keep a fallback path you've actually tested.
Teams that do this usually find the gap between providers is smaller than the marketing suggests and larger than their first demo implied — and that the operational details, not the model quality, determine whether the integration succeeds. Whether you land on Kimi K3.1 Pro, DeepSeek v3 or r1 directly, or a managed route like Mydeepseekapi, the discipline of measuring before committing is what keeps the decision correct twelve months later, when both models have shipped new versions and your traffic profile has changed.