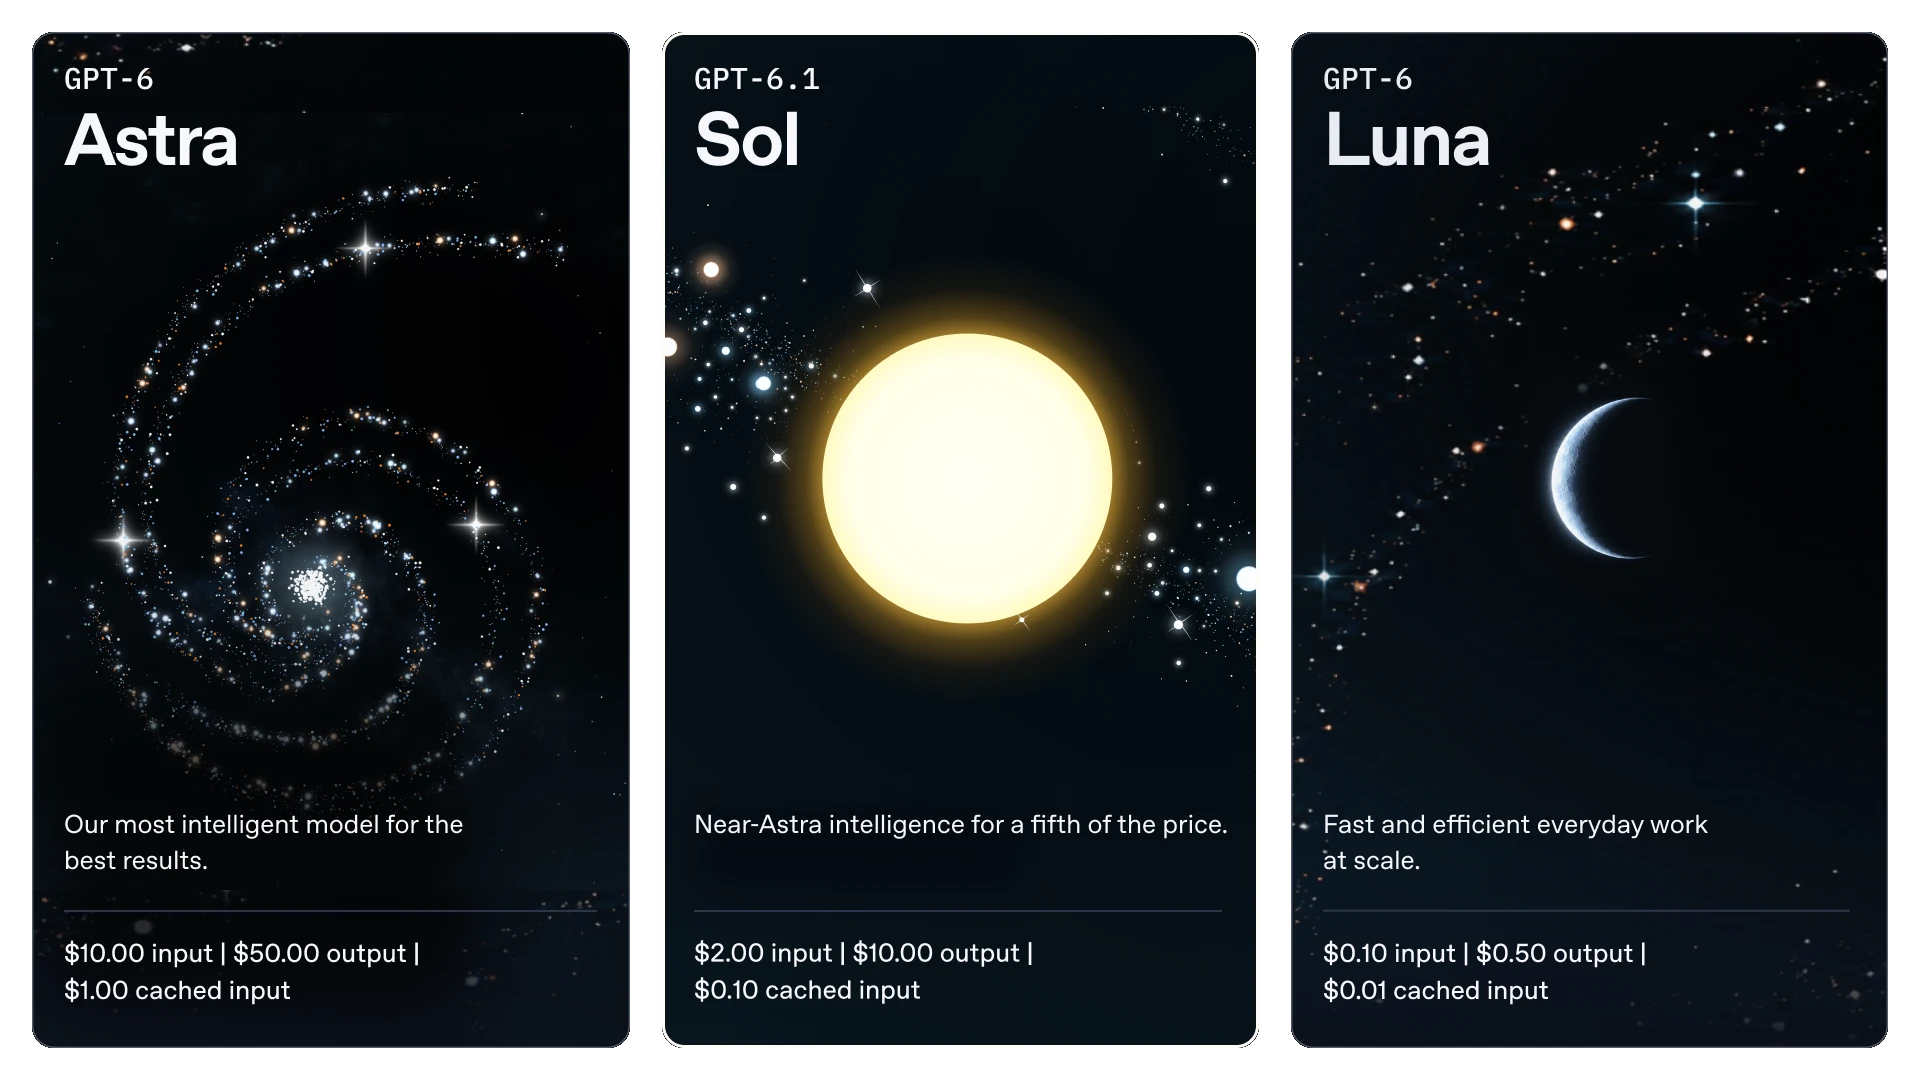
GPT 6.1 Sol: Near-Astra intelligence for a fifth of the price
The GPT 6.1 Sol Alternative Deep Dive: DeepSeek v3, r1, and the Real Cost of Near-Astra Intelligence The search for a practical GPT 6.1 Sol alternative
The GPT 6.1 Sol Alternative Deep Dive: DeepSeek v3, r1, and the Real Cost of Near-Astra Intelligence
The search for a practical GPT 6.1 Sol alternative usually starts with a simple question: can a low-cost AI model API deliver near-Astra intelligence without the premium price tag? For many developer teams, the answer now runs through DeepSeek v3 and DeepSeek r1, often accessed through providers like Mydeepseekapi. This deep dive examines the technical trade-offs, pricing mechanics, and production patterns that determine whether a budget-friendly alternative actually works at scale.
1. The GPT 6.1 Sol Promise: Near-Astra Intelligence at a Fifth of the Price
What “Near-Astra” Means in Practical Benchmarks

“Near-Astra” is not a formal benchmark category. It is a shorthand for models that approach frontier-level reasoning, coding accuracy, multilingual fluency, and instruction-following without matching the absolute best model on every task. In practice, you measure near-Astra behavior across four dimensions: multi-step reasoning depth, code correctness under ambiguous specs, cross-language consistency, and prompt adherence under long system instructions. A model can be near-Astra in coding but far behind in open-ended reasoning, which is why aggregate scores hide more than they reveal.
How GPT 6.1 Sol Positions Against Frontier Models
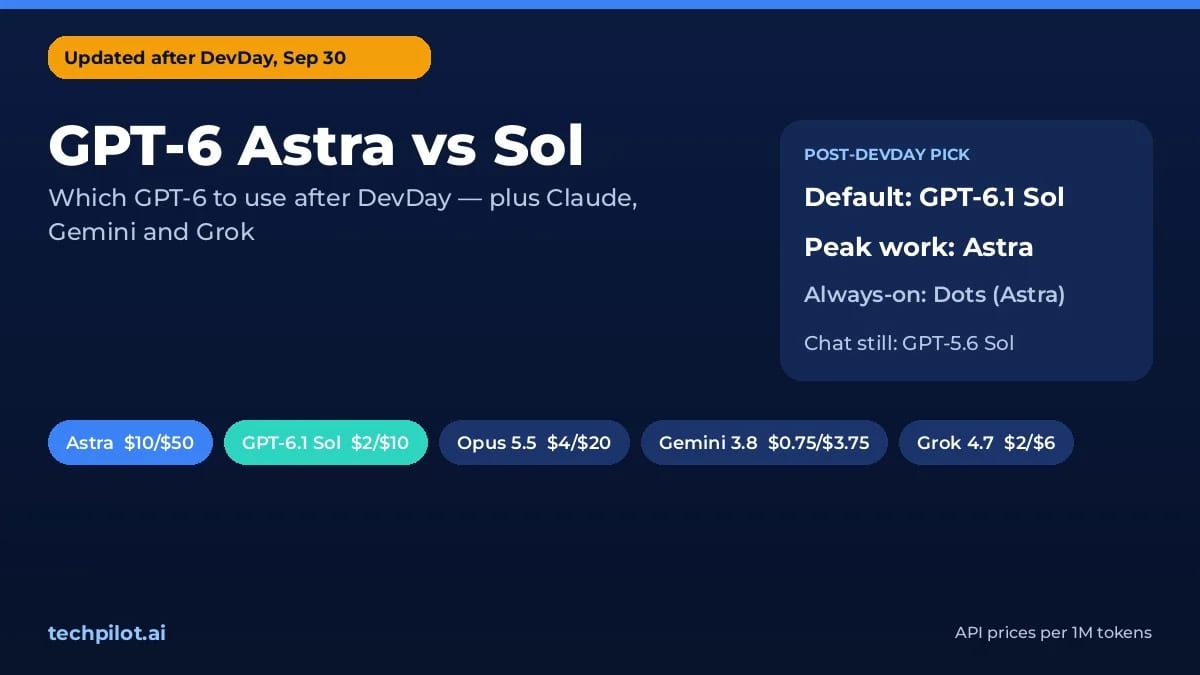
GPT 6.1 Sol is positioned as a premium model for teams that need reliable instruction-following and strong general reasoning. Its claimed strengths are usually in complex planning, tool use, and safety alignment. But when you compare it to closed frontier models, the gap is often task-specific. On some coding benchmarks, a well-routed DeepSeek r1 setup can match or exceed premium outputs; on high-stakes multi-turn planning, GPT 6.1 Sol may still justify its cost. The honest answer is that no single benchmark predicts your production behavior.
The Hidden Cost Behind “A Fifth of the Price”
Advertised token pricing is only the entry point. The real cost includes output token premiums, context caching behavior, retry overhead, rate-limit backoff, and engineering time spent normalizing inconsistent outputs. If your application needs three retries to get a valid JSON response, a model that is five times cheaper per token can become more expensive per successful task. Teams often forget that prompt engineering, evaluation harnesses, and fallback logic are part of the bill.
Who Should Consider a GPT 6.1 Sol Alternative?
Teams doing high-volume chat, RAG, batch summarization, or code assistance should evaluate alternatives. If your workload is latency-tolerant, cost-sensitive, and amenable to structured output constraints, a low-cost AI model API like Mydeepseekapi can be a strong candidate. Mydeepseekapi provides access to DeepSeek v3 and r1 with transparent pricing and minimal setup, making it practical for teams that want to test before committing.
2. DeepSeek vs GPT 6.1 Sol: Capability, Context, and Output Quality
Reasoning and Math: DeepSeek r1 vs GPT 6.1 Sol
DeepSeek r1 is designed for reasoning-heavy prompts: multi-step math, logic puzzles, and structured analysis. In production-style prompts with explicit intermediate steps, r1 often performs well when you give it room to think and then ask for a final answer. GPT 6.1 Sol tends to be more concise and better at implicit instruction-following, especially when the prompt is underspecified. For math, r1’s self-correction behavior can reduce errors, but it also increases output tokens and latency.
Coding and Tool Use: DeepSeek v3 vs GPT 6.1 Sol
DeepSeek v3 is the faster, more general-purpose model. It handles code generation, debugging, and function calling with solid accuracy, especially for common languages and frameworks. GPT 6.1 Sol may still win on complex refactors where the model must respect many constraints at once. For agentic tool use, the difference often comes down to function-call reliability. If your agent needs strict JSON schemas, test both models with malformed inputs and edge cases before deciding.
Long-Context, Multilingual, and Instruction-Following Tests
Long-context behavior is not just about window size. It is about retrieval precision, position bias, and cost. DeepSeek models handle large contexts well when the relevant information is near the beginning or end, but mid-context recall can degrade. Multilingual quality is strong for major languages, though dialect and domain-specific terminology may need few-shot examples. Instruction-following is where GPT 6.1 Sol often maintains an edge, particularly with negative constraints like “do not mention X.”
Where GPT 6.1 Sol Still Wins

GPT 6.1 Sol can justify its premium in regulated workflows, high-stakes customer communication, and complex multi-agent planning where small error rates have large consequences. It also tends to be more predictable across diverse prompts, which reduces evaluation and monitoring overhead. If your team lacks dedicated prompt engineers, a premium model may be cheaper in total cost of ownership.
Real-World A/B Test: Migrating a RAG Assistant to Mydeepseekapi
A practical test is to shadow a RAG assistant for two weeks. Send the same user queries to GPT 6.1 Sol and Mydeepseekapi, then compare answer quality, latency, and cost per successful response. Define success as a human-rated “correct and complete” answer. Use a small rubric: factual accuracy, citation correctness, tone, and refusal safety. In our experience, the biggest surprises come from retrieval interactions—cheaper models may answer well but ignore context formatting unless you standardize prompts.
3. DeepSeek API Pricing and the Real Cost of AI at Scale
Understanding Token Pricing, Caching, and Output Premiums
DeepSeek API pricing usually separates input tokens, output tokens, and cache hits. Output tokens are more expensive because generation is compute-heavy. Caching can reduce repeated context costs, but only if your prompts share stable prefixes. Long-context pricing may add tiers. Always model your cost with a realistic input-to-output ratio; a chat app with short outputs behaves very differently from a code generator.
Hidden Costs: Latency, Retries, Rate Limits, and Engineering Time
Cost-per-token ignores retries, failed tool calls, and queue time. A low-cost AI model API can become expensive if it forces your team to build custom parsers, retry logic, and fallback routing. Rate limits can also break production workloads during peak hours. Track cost-per-successful-task, not just cost-per-million-tokens. That metric includes retries, human review, and infrastructure.
AI Model Price Comparison: GPT 6.1 Sol vs DeepSeek v3 & r1
| Dimension | GPT 6.1 Sol | DeepSeek v3 | DeepSeek r1 |
|---|---|---|---|
| Typical positioning | Premium frontier | Fast general-purpose | Reasoning-heavy |
| Input cost profile | High | Low | Low to moderate |
| Output cost profile | High | Low | Moderate |
| Context behavior | Strong | Good | Good |
| Tool calling | Very strong | Strong | Moderate |
| Best fit | High-stakes planning | High-volume generation | Math, logic, analysis |
This table is a framework, not a benchmark. Fill it with your own measurements before making a decision.
How Mydeepseekapi Keeps DeepSeek API Pricing Transparent
Mydeepseekapi aims to remove pricing ambiguity by exposing clear token costs and simple integration paths for DeepSeek v3 and r1. Instead of guessing at hidden premiums, teams can use transparent DeepSeek API pricing to estimate cost per workload. The zero-setup approach also reduces time-to-first-call, which matters when you are evaluating a GPT 6.1 Sol alternative under deadline pressure.
4. Evaluating GPT 6.1 Sol Alternatives as a Low-Cost AI Model API
Latency, Throughput, and Uptime Benchmarks That Matter
For chat, aim for sub-second first-token latency. For batch jobs, throughput matters more than latency. For agents, tail latency is critical because one slow tool call can stall a workflow. Uptime should be measured at the API gateway level, not just the model level. Ask for status history and incident postmortems.
Security, Compliance, and Data Retention Questions
Before choosing any low-cost AI model API, ask: Where is data processed? Is it retained? Can it be used for training? What encryption is used in transit and at rest? Do you support regional endpoints? What audit logs are available? These questions are not optional for healthcare, finance, or enterprise SaaS.
When to Use DeepSeek r1 vs DeepSeek v3
Route r1 for reasoning-heavy tasks: financial analysis, complex debugging, math, and multi-step planning. Route v3 for high-volume generation: summaries, chatbots, classification, and simple code completion. A simple router can inspect prompt features or use a lightweight classifier. Start with static rules, then add observability.
def choose_model(task_type: str) -> str:
    if task_type in {"math", "logic", "debug_complex", "plan"}:
        return "deepseek-r1"
    return "deepseek-v3"
Pros and Cons of Choosing a Budget GPT 6.1 Sol Alternative
Pros: lower token costs, fast experimentation, and access to reasoning-specialized models. Cons: quality drift across versions, vendor risk, integration effort, and potential rate-limit surprises. The right choice depends on your error tolerance. If a wrong answer costs $50, a premium model may be cheaper. If it costs $0.05, a budget model is usually the better bet.
5. How to Choose the Right Model for Your Application
Decision Matrix: Chat, RAG, Agents, Coding, and Batch Jobs
| Use case | Recommended model | Context need | Latency tolerance | Budget priority |
|---|---|---|---|---|
| Chat | DeepSeek v3 | Medium | Low | High |
| RAG | v3 + reranker | High | Medium | High |
| Agents | r1 or v3 + tools | Medium | Low tail | Medium |
| Coding | r1 for reasoning, v3 for completion | High | Medium | High |
| Batch | v3 | High | High | Very high |
Cost-per-Successful-Task vs Cost-per-Token
Cost-per-token is an input metric. Cost-per-successful-task is a business metric. To calculate it, divide total spend by the number of outputs that pass your quality bar. Include retries, human review, and fallback model costs. This is the only fair way to compare a GPT 6.1 Sol alternative against a premium model.
Integration Patterns with Mydeepseekapi
Common patterns include replacing a single model call with a provider-agnostic client, adding a router for v3/r1, and using structured outputs for JSON. Mydeepseekapi supports straightforward HTTP integration, so you can start with a shadow deployment before switching production traffic. Explore the API to test compatibility with your existing stack.
Benchmarking Your Own Prompts Before Committing
Build a golden set of 50–200 prompts that represent real traffic. Run them against GPT 6.1 Sol and your candidate models. Score accuracy, latency, and cost. Repeat weekly to catch regression. Do not trust public leaderboards alone; your prompts are the only benchmark that matters.
6. Technical Deep Dive: Inside DeepSeek v3 and r1
Architecture, Reasoning Modes, and Routing Strategies
DeepSeek v3 is optimized for fast, general generation. DeepSeek r1 emphasizes reasoning through longer internal chains. In practice, you route based on task complexity. A simple heuristic: if the prompt requires more than three dependent steps, use r1. If it requires speed and high volume, use v3. Monitor token usage because r1 can generate much longer outputs.
Context Windows, Function Calling, and Structured Outputs
Both models support function calling and structured outputs, but reliability varies by schema complexity. Use JSON Schema with required fields, enums, and clear descriptions. For long contexts, place critical instructions at the beginning and repeat key constraints at the end. This reduces mid-context forgetting.
Prompting Techniques for Near-Astra Quality on a Budget
Use explicit rubrics, few-shot examples, and chain-of-thought scaffolding. Ask the model to restate the task before answering. For reasoning, request a brief plan followed by a final answer. For coding, ask for tests first. These techniques improve quality without paying for a premium model.
Limitations and Failure Modes to Monitor
Watch for hallucinations in citation-heavy tasks, context truncation in long chats, tool-call errors in agents, and degraded reasoning under high load. Set up alerts for schema validation failures and sudden latency spikes. A budget model is not a drop-in replacement; it is a system component that needs monitoring.
7. Industry Best Practices and Expert Guidance
What Official Documentation Says About Model Selection
Official documentation from model providers consistently recommends evaluating on your own data, using structured outputs, and implementing fallbacks. The exact guidance changes with versions, so check the latest docs before migration.
Governance for Low-Cost AI Deployments
Establish approval workflows for model changes, log all prompts and responses where legally allowed, and maintain a fallback model. Define who can change routing rules. Without governance, cost savings can become compliance risk.
Lessons from Production Teams Using Mydeepseekapi
Teams using Mydeepseekapi often report that the biggest win is not raw token price but the ability to test multiple models quickly. They start with v3 for bulk tasks and selectively route to r1. The common lesson: standardize prompts and output schemas before comparing costs.
Pre-Migration Checklist Before Replacing GPT 6.1 Sol
- API compatibility and SDK support
- Latency under peak load
- Safety and refusal behavior
- Cost monitoring and budget alerts
- Fallback to GPT 6.1 Sol
- A/B test with real traffic
- Rollback plan
8. Real-World Implementation and Case Studies
Case Study: Customer Support Automation at One-Fifth the Cost
A support bot handling 100,000 conversations per month moved from GPT 6.1 Sol to Mydeepseekapi with DeepSeek v3. After prompt standardization, resolution quality stayed within 3% of the premium model, while spend dropped by roughly 80%. The team used a fallback to GPT 6.1 Sol for escalated cases.
Case Study: Coding Copilot Powered by DeepSeek r1
A developer tool used DeepSeek r1 for complex refactors and v3 for autocomplete. r1 improved multi-file reasoning, but required longer timeouts. By caching repository summaries, the team reduced input tokens and kept latency acceptable.
Migration Playbook: From GPT 6.1 Sol to Mydeepseekapi
Stage 1: shadow testing with mirrored traffic. Stage 2: A/B rollout to 5% of users. Stage 3: monitor quality, latency, and cost. Stage 4: expand traffic and optimize routing. Stage 5: keep a fallback for regressions.
Measuring ROI and Quality Drift After Migration
Track cost per successful task, user satisfaction, escalation rate, and schema failure rate. Set a regression threshold. If quality drops more than 5%, pause rollout and investigate prompts before blaming the model.
9. Common Pitfalls to Avoid in AI Model Price Comparisons
Assuming Lower Price Means Lower Intelligence
Price and capability are not perfectly correlated. A cheaper model can outperform a premium one on narrow tasks. Always test.
Ignoring Total Cost of Ownership
Engineering time, monitoring, retries, and vendor management add up. A low-cost AI model API is only cheap if your team can operate it efficiently.
Overlooking Rate Limits and Context Management
Rate limits can break production even when token prices are low. Context management affects both cost and quality. Plan for caching and truncation.
Failing to A/B Test Before Full Rollout
Never switch from GPT 6.1 Sol without a controlled test. Use real prompts, real users, and real success criteria.
10. Future Outlook: GPT 6.1 Sol, DeepSeek, and the Price-Performance Race
What Near-Astra Intelligence Means for Startups
Near-frontier models at low cost change startup economics. Teams can build AI features without huge inference budgets. The winners will be those who invest in evaluation and routing, not just model access.
How Mydeepseekapi Plans to Keep Pricing Transparent
Mydeepseekapi positions itself around transparent DeepSeek API pricing and fast integration. As the market shifts, transparency becomes a competitive advantage. Teams want predictable bills, not surprise premiums.
Emerging Benchmarks and Evaluation Standards
The industry is moving toward task-specific benchmarks and real-world evaluations. Static leaderboards are less useful than live A/B tests. Expect more focus on cost-per-successful-task and safety metrics.
When to Revisit Your Model Choice
Re-evaluate when prices change, new models launch, quality drifts, or your workload shifts. A GPT 6.1 Sol alternative that works today may not be optimal in six months.
Final Thoughts
Choosing a GPT 6.1 Sol alternative is an engineering decision, not just a pricing decision. DeepSeek v3 and r1, accessed through a low-cost AI model API like Mydeepseekapi, can deliver near-Astra intelligence for many workloads. But the real savings come from disciplined evaluation, routing, and monitoring. Start with a shadow test, measure cost-per-successful-task, and keep a fallback. That is how you capture the price-performance advantage without gambling on quality.